 Orchestra Research

From the README
How to use AI-Research-SKILLs
AI Research Skills Library
The most comprehensive open-source skills library enabling AI agents to autonomously conduct AI research — from idea to paper


98 Skills Powering AI Research in 2026
View All 23 Categories
| Autoresearch (1) | Ideation (2) | ML Paper Writing (2) |
| Model Architecture (5) | Fine-Tuning (4) | Post-Training (8) |
| Distributed Training (6) | Optimization (6) | Inference (4) |
| Tokenization (2) | Data Processing (2) | Evaluation (3) |
| Safety & Alignment (4) | Agents (4) | RAG (5) |
| Multimodal (7) | Prompt Engineering (4) | MLOps (3) |
| Observability (2) | Infrastructure (3) | Mech Interp (4) |
| Emerging Techniques (6) | Agent-Native Research Artifact (3) |
Table of Contents
- Our Mission
- Path Towards AI Research Agent
- Available AI Research Engineering Skills
- Demos
- Skill Structure
- Roadmap
- Repository Structure
- Use Cases
- Contributors
- Citation
- Community
Our Mission
We enable AI agents to autonomously conduct AI research — from literature survey and idea generation through experiment execution to paper writing. The library provides both the research orchestration layer (autoresearch, ideation, paper writing) and the engineering skills (training, evaluation, deployment) needed at each stage.
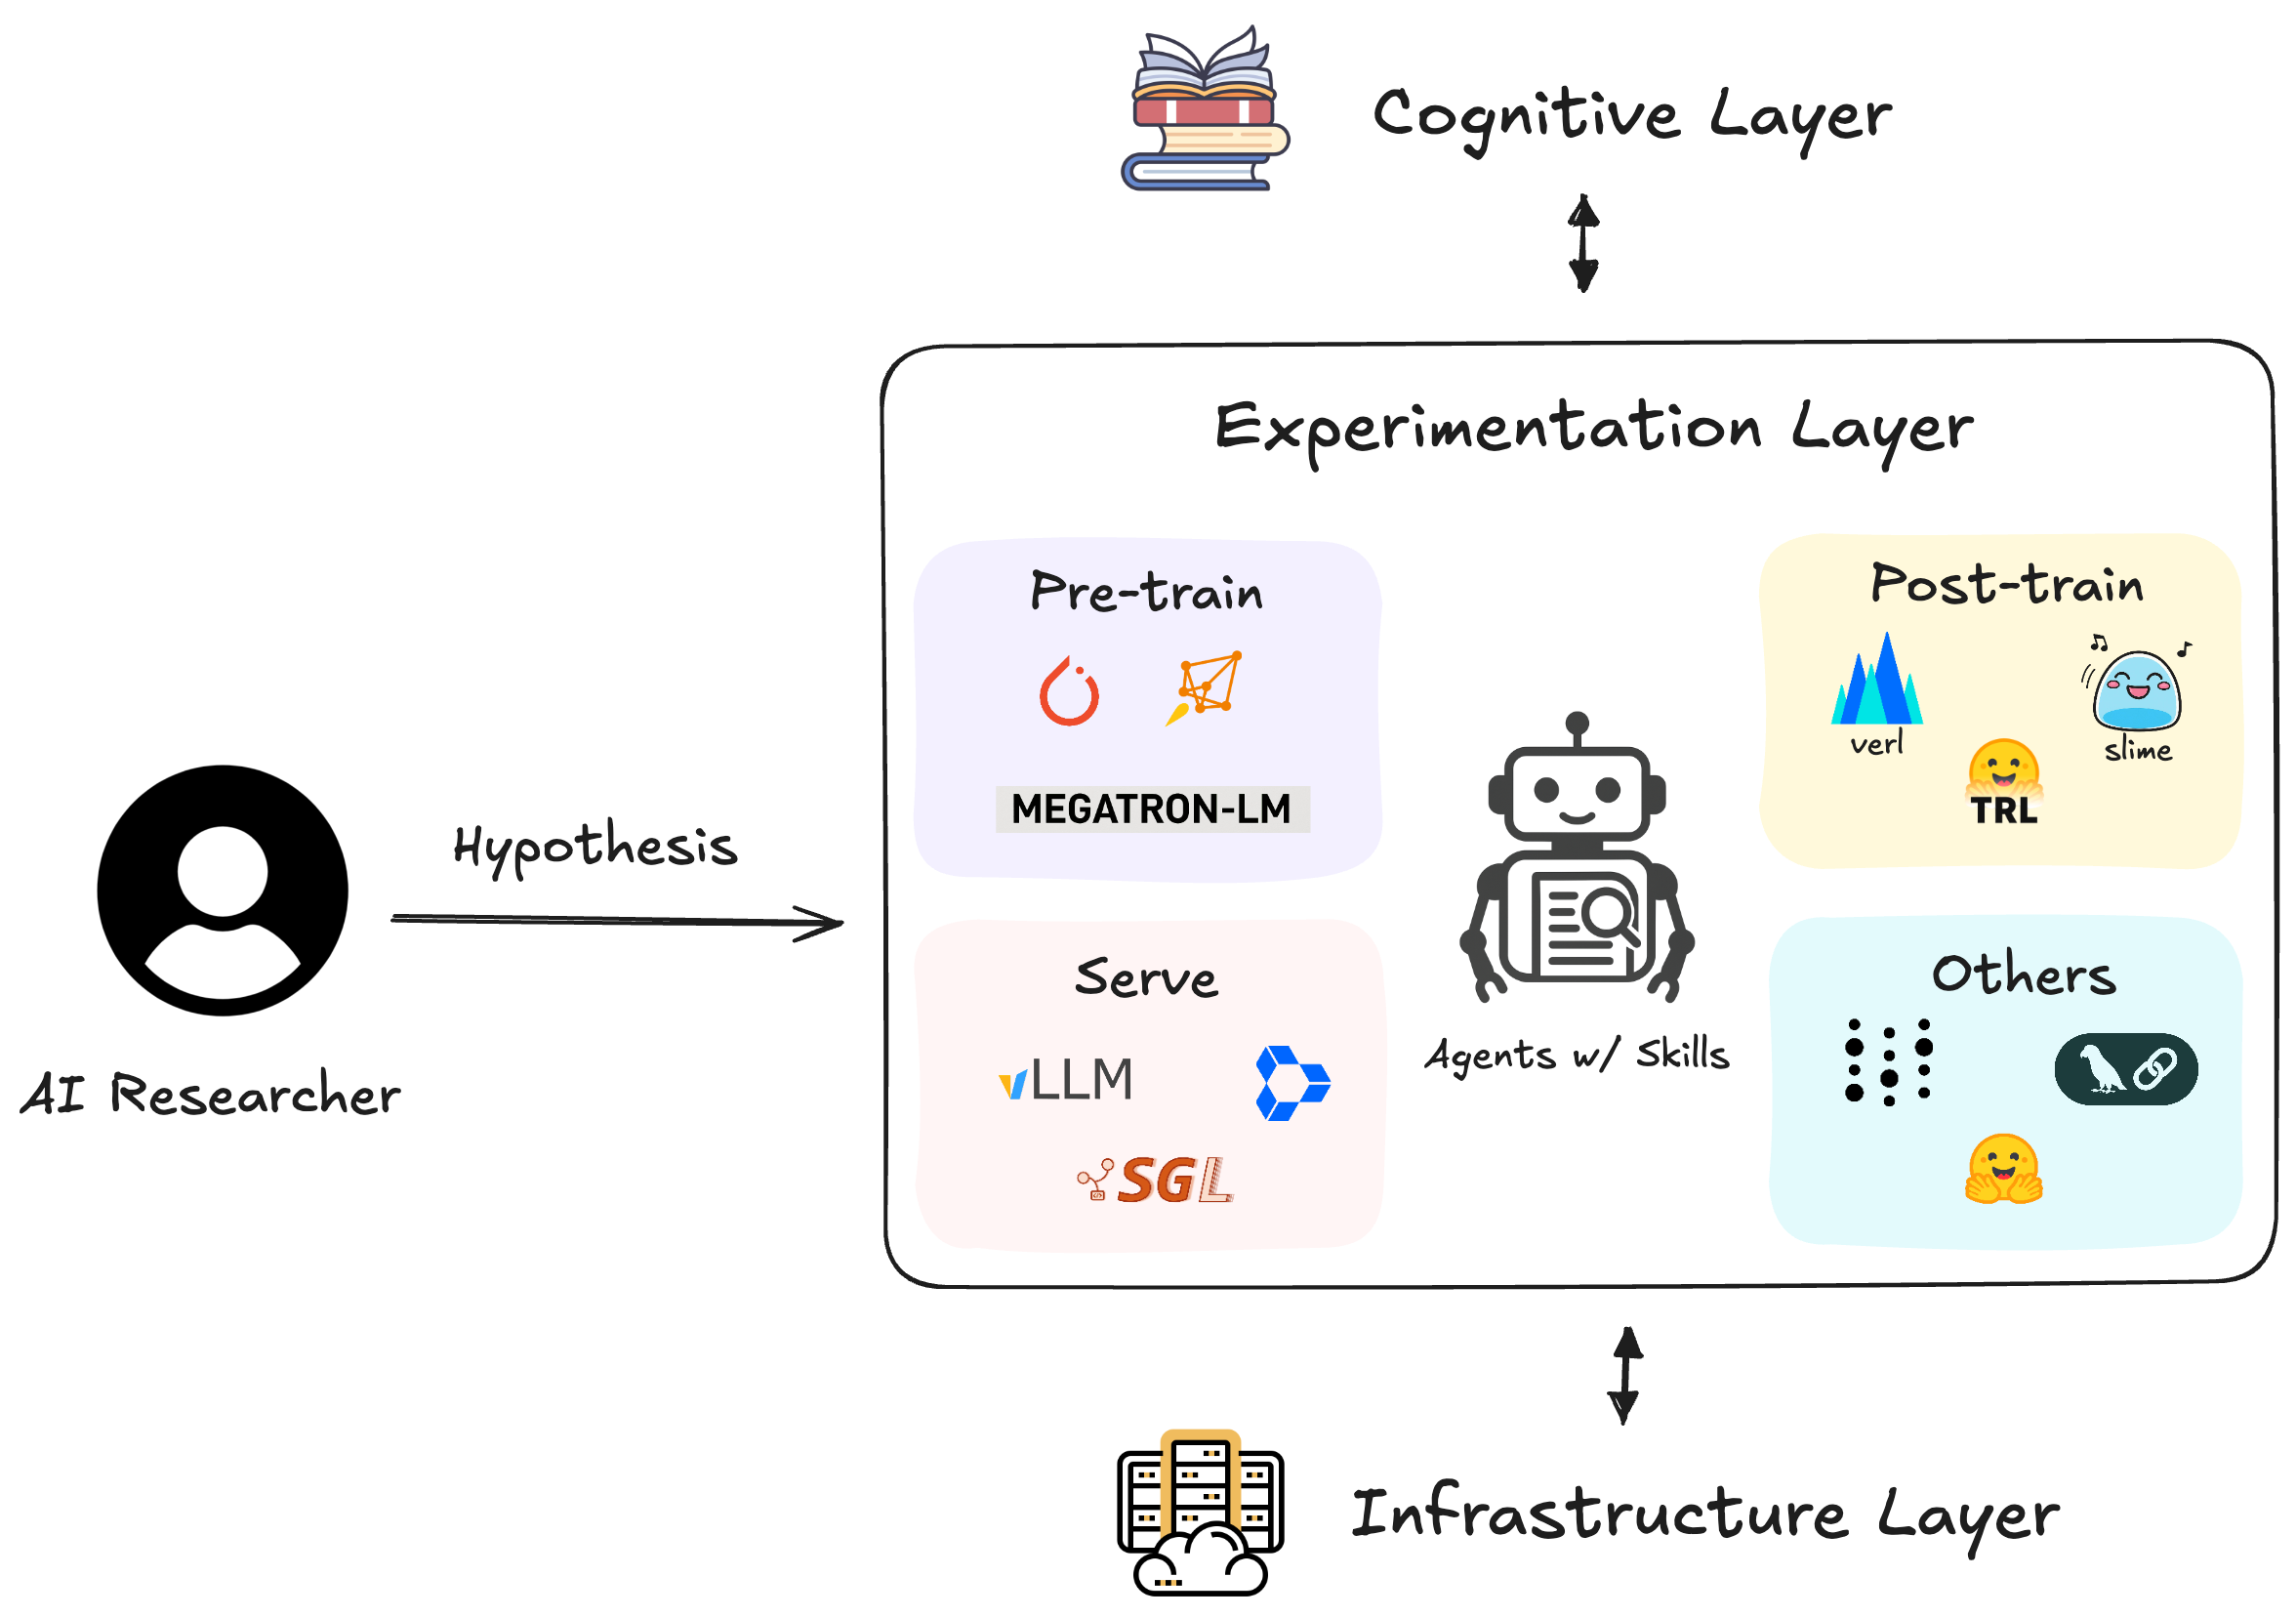
System diagram of an AI research agent
Path Towards AI Research Agent
Modern AI research requires mastering dozens of specialized tools and frameworks. AI Researchers spend more time debugging infrastructure than testing hypotheses — slowing the pace of scientific discovery. We provide a comprehensive skills library that enables AI agents to autonomously conduct the full research lifecycle — from brainstorming ideas to writing the paper.
- Autonomous Research - The autoresearch skill orchestrates the entire research workflow using a two-loop architecture, routing to domain skills as needed
- Specialized Expertise - Each domain skill provides deep, production-ready knowledge of a specific framework (Megatron-LM, vLLM, TRL, etc.)
- End-to-End Coverage - 98 skills spanning the full AI research lifecycle, from ideation and literature survey to experiments and paper writing
- Research-Grade Quality - Documentation sourced from official repos, real GitHub issues, and battle-tested production workflows
Available AI Research Engineering Skills
Quality over quantity: Each skill provides comprehensive, expert-level guidance with real code examples, troubleshooting guides, and production-ready workflows.
📦 Quick Install (Recommended)
For humans — interactive installer with one command:
npx @orchestra-research/ai-research-skills
For AI agents — point your agent to the welcome doc and it handles the rest:
Read https://www.orchestra-research.com/ai-research-skills/welcome.md and follow the instructions to install and use AI Research Skills.
This installs all 98 skills, loads the autoresearch orchestration layer, and starts autonomous research.
What the installer does
- Auto-detects your installed coding agents (Claude Code, Hermes Agent, OpenCode, Qoder, Cursor, Gemini CLI, etc.)
- Installs skills to
~/.orchestra/skills/with symlinks to each agent (falls back to copy on Windows) - Offers everything, quickstart bundle, by category, or individual skills
- Updates installed skills with latest versions
- Uninstalls all or selected skills
CLI Commands
# Interactive installer (recommended)
npx @orchestra-research/ai-research-skills

# Direct commands
npx @orchestra-research/ai-research-skills list      # View installed skills
npx @orchestra-research/ai-research-skills update    # Update installed skills
Claude Code Marketplace (Alternative)
Install skill categories directly using the Claude Code CLI:
# Add the marketplace
/plugin marketplace add orchestra-research/AI-research-SKILLs

# Install by category (23 categories available)
/plugin install fine-tuning@ai-research-skills        # Axolotl, LLaMA-Factory, PEFT, Unsloth
/plugin install post-training@ai-research-skills      # TRL, GRPO, OpenRLHF, SimPO, verl, slime, miles, torchforge
/plugin install inference-serving@ai-research-skills  # vLLM, TensorRT-LLM, llama.cpp, SGLang
/plugin install distributed-training@ai-research-skills
/plugin install optimization@ai-research-skills
All 23 Categories (98 Skills)
| Category | Skills | Included |
|---|---|---|
| Autoresearch | 1 | Autonomous research orchestration — central layer that manages the full lifecycle and routes to all other skills |
| Ideation | 2 | Research Brainstorming, Creative Thinking |
| ML Paper Writing | 2 | ML Paper Writing (LaTeX templates, citation verification), Academic Plotting |
| Model Architecture | 5 | LitGPT, Mamba, NanoGPT, RWKV, TorchTitan |
| Tokenization | 2 | HuggingFace Tokenizers, SentencePiece |
| Fine-Tuning | 4 | Axolotl, LLaMA-Factory, PEFT, Unsloth |
| Mech Interp | 4 | TransformerLens, SAELens, pyvene, nnsight |
| Data Processing | 2 | NeMo Curator, Ray Data |
| Post-Training | 8 | TRL, GRPO, OpenRLHF, SimPO, verl, slime, miles, torchforge |
| Safety | 4 | Constitutional AI, LlamaGuard, NeMo Guardrails, Prompt Guard |
| Distributed | 6 | DeepSpeed, FSDP, Accelerate, Megatron-Core, Lightning, Ray Train |
| Infrastructure | 3 | Modal, Lambda Labs, SkyPilot |
| Optimization | 6 | Flash Attention, bitsandbytes, GPTQ, AWQ, HQQ, GGUF |
| Evaluation | 3 | lm-eval-harness, BigCode, NeMo Evaluator |
| Inference | 4 | vLLM, TensorRT-LLM, llama.cpp, SGLang |
| MLOps | 3 | W&B, MLflow, TensorBoard |
| Agents | 4 | LangChain, LlamaIndex, CrewAI, AutoGPT |
| RAG | 5 | Chroma, FAISS, Pinecone, Qdrant, Sentence Transformers |
| Prompt Eng | 4 | DSPy, Instructor, Guidance, Outlines |
| Observability | 2 | LangSmith, Phoenix |
| Multimodal | 7 | CLIP, Whisper, LLaVA, BLIP-2, SAM, Stable Diffusion, AudioCraft |
| Emerging | 6 | MoE, Model Merging, Long Context, Speculative Decoding, Distillation, Pruning |
| Agent-Native Research Artifact | 3 | ARA Compiler, Research Manager, Rigor Reviewer |
View All 98 Skills in Details
🔬 Autoresearch (1 skill) — Central Orchestration Layer
- Autoresearch - Autonomous research orchestration using a two-loop architecture (inner optimization + outer synthesis). Manages the full lifecycle from literature survey to paper writing, routing to all domain-specific skills. Supports Claude Code /loop and OpenClaw heartbeat for continuous operation (390 lines + 3 refs)
🏗️ Model Architecture (5 skills)
- LitGPT - Lightning AI's 20+ clean LLM implementations with production training recipes (462 lines + 4 refs)
- Mamba - State-space models with O(n) complexity, 5× faster than Transformers (253 lines + 3 refs)
- RWKV - RNN+Transformer hybrid, infinite context, Linux Foundation project (253 lines + 3 refs)
- NanoGPT - Educational GPT in ~300 lines by Karpathy (283 lines + 3 refs)
- TorchTitan - PyTorch-native distributed training for Llama 3.1 with 4D parallelism
🔤 Tokenization (2 skills)
- HuggingFace Tokenizers - Rust-based, <20s/GB, BPE/WordPiece/Unigram algorithms (486 lines + 4 refs)
- SentencePiece - Language-independent, 50k sentences/sec, used by T5/ALBERT (228 lines + 2 refs)
🎯 Fine-Tuning (4 skills)
- Axolotl - YAML-based fine-tuning with 100+ models (156 lines + 4 refs)
- LLaMA-Factory - WebUI no-code fine-tuning (78 lines + 5 refs)
- Unsloth - 2x faster QLoRA fine-tuning (75 lines + 4 refs)
- PEFT - Parameter-efficient fine-tuning with LoRA, QLoRA, DoRA, 25+ methods (431 lines + 2 refs)
🔬 Mechanistic Interpretability (4 skills)
- TransformerLens - Neel Nanda's library for mech interp with HookPoints, activation caching (346 lines + 3 refs)
- SAELens - Sparse Autoencoder training and analysis for feature discovery (386 lines + 3 refs)
- pyvene - Stanford's causal intervention library with declarative configs (473 lines + 3 refs)
- nnsight - Remote interpretability via NDIF, run experiments on 70B+ models (436 lines + 3 refs)
📊 Data Processing (2 skills)
- Ray Data - Distributed ML data processing, streaming execution, GPU support (318 lines + 2 refs)
- NeMo Curator - GPU-accelerated data curation, 16× faster deduplication (375 lines + 2 refs)
🎓 Post-Training (8 skills)
- TRL Fine-Tuning - Transformer Reinforcement Learning (447 lines + 4 refs)
- GRPO-RL-Training (TRL) - Group Relative Policy Optimization with TRL (569 lines, gold standard)
- OpenRLHF - Full RLHF pipeline with Ray + vLLM (241 lines + 4 refs)
- SimPO - Simple Preference Optimization, no reference model needed (211 lines + 3 refs)
- verl - ByteDance's HybridFlow RL framework, FSDP/Megatron + vLLM/SGLang backends (389 lines + 2 refs)
- slime - THUDM's Megatron+SGLang framework powering GLM-4.x models (464 lines + 2 refs)
- miles - Enterprise fork of slime with FP8, INT4, speculative RL for MoE training (315 lines + 2 refs)
- torchforge - Meta's PyTorch-native RL with Monarch+TorchTitan+vLLM (380 lines + 2 refs)
🛡️ Safety & Alignment (4 skills)
- Constitutional AI - AI-driven self-improvement via principles (282 lines)
- LlamaGuard - Safety classifier for LLM inputs/outputs (329 lines)
- NeMo Guardrails - Programmable guardrails with Colang (289 lines)
- Prompt Guard - Meta's 86M prompt injection & jailbreak detector, 99%+ TPR, <2ms GPU (313 lines)
⚡ Distributed Training (6 skills)
- Megatron-Core - NVIDIA's framework for training 2B-462B param models with 47% MFU on H100 (359 lines + 4 refs)
- DeepSpeed - Microsoft's ZeRO optimization (137 lines + 9 refs)
- PyTorch FSDP2 - Fully Sharded Data Parallel v2 with
fully_shardand DTensor (231 lines + 12 refs) - Accelerate - HuggingFace's 4-line distributed training API (324 lines + 3 refs)
- PyTorch Lightning - High-level training framework with Trainer class (339 lines + 3 refs)
- Ray Train - Multi-node orchestration and hyperparameter tuning (399 lines + 1 ref)
🚀 Optimization (6 skills)
- Flash Attention - 2-4x faster attention with memory efficiency (359 lines + 2 refs)
- bitsandbytes - 8-bit/4-bit quantization for 50-75% memory reduction (403 lines + 3 refs)
- GPTQ - 4-bit post-training quantization, 4× memory reduction, <2% accuracy loss (443 lines + 3 refs)
- AWQ - Activation-aware weight quantization, 4-bit with minimal accuracy loss (310 lines + 2 refs)
- HQQ - Half-Quadratic Quantization, no calibration data needed, multi-backend (370 lines + 2 refs)
- GGUF - llama.cpp quantization format, K-quant methods, CPU/Metal inference (380 lines + 2 refs)
📊 Evaluation (3 skills)
- lm-evaluation-harness - EleutherAI's standard for benchmarking LLMs across 60+ tasks (482 lines + 4 refs)
- BigCode Evaluation Harness - Code model benchmarking with HumanEval, MBPP, MultiPL-E, pass@k metrics (406 lines + 3 refs)
- NeMo Evaluator - NVIDIA's enterprise platform for 100+ benchmarks across 18+ harnesses with multi-backend execution (454 lines + 4 refs)
☁️ Infrastructure (3 skills)
- Modal - Serverless GPU cloud with Python-native API, T4-H200 on-demand (342 lines + 2 refs)
- SkyPilot - Multi-cloud orchestration across 20+ providers with spot recovery (390 lines + 2 refs)
- Lambda Labs - Reserved/on-demand GPU cloud with H100/A100, persistent filesystems (390 lines + 2 refs)
🔥 Inference & Serving (4 skills)
- vLLM - High-throughput LLM serving with PagedAttention (356 lines + 4 refs, production-ready)
- TensorRT-LLM - NVIDIA's fastest inference, 24k tok/s, FP8/INT4 quantization (180 lines + 3 refs)
- llama.cpp - CPU/Apple Silicon inference, GGUF quantization (251 lines + 3 refs)
- SGLang - Structured generation with RadixAttention, 5-10× faster for agents (435 lines + 3 refs)
🤖 Agents (4 skills)
- LangChain - Most popular agent framework, 500+ integrations, ReAct pattern (658 lines + 3 refs, production-ready)
- LlamaIndex - Data framework for LLM apps, 300+ connectors, RAG-focused (535 lines + 3 refs)
- CrewAI - Multi-agent orchestration, role-based collaboration, autonomous workflows (498 lines + 3 refs)
- AutoGPT - Autonomous AI agent platform, visual workflow builder, continuous execution (400 lines + 2 refs)
🔍 RAG (5 skills)
- Chroma - Open-source embedding database, local/cloud, 24k stars (385 lines + 1 ref)
- FAISS - Facebook's similarity search, billion-scale, GPU acceleration (295 lines)
- Sentence Transformers - 5000+ embedding models, multilingual, 15k stars (370 lines)
- Pinecone - Managed vector database, auto-scaling, <100ms latency (410 lines)
- Qdrant - High-performance vector search, Rust-powered, hybrid search with filtering (493 lines + 2 refs)
🎨 Multimodal (7 skills)
- CLIP - OpenAI's vision-language model, zero-shot classification, 25k stars (320 lines)
- Whisper - Robust speech recognition, 99 languages, 73k stars (395 lines)
- LLaVA - Vision-language assistant, image chat, GPT-4V level (360 lines)
- Stable Diffusion - Text-to-image generation via HuggingFace Diffusers, SDXL, ControlNet (380 lines + 2 refs)
- Segment Anything - Meta's SAM for zero-shot image segmentation with points/boxes (500 lines + 2 refs)
- BLIP-2 - Vision-language pretraining with Q-Former, image captioning, VQA (500 lines + 2 refs)
- AudioCraft - Meta's MusicGen/AudioGen for text-to-music and text-to-sound (470 lines + 2 refs)
🎯 Prompt Engineering (4 skills)
- DSPy - Declarative prompt programming with optimizers, Stanford NLP, 22k stars (438 lines + 3 refs)
- Instructor - Structured LLM outputs with Pydantic validation, 15k stars (726 lines + 3 refs)
- Guidance - Constrained generation with regex/grammars, Microsoft Research, 18k stars (485 lines + 3 refs)
- Outlines - Structured text with FSM, zero-overhead, 8k stars (601 lines + 3 refs)
📊 MLOps (3 skills)
- Weights & Biases - Experiment tracking, sweeps, artifacts, model registry (427 lines + 3 refs)
- MLflow - Model registry, tracking, deployment, autologging (514 lines + 3 refs)
- TensorBoard - Visualization, profiling, embeddings, scalars/images (538 lines + 3 refs)
👁️ Observability (2 skills)
- LangSmith - LLM observability, tracing, evaluation, monitoring for AI apps (422 lines + 2 refs)
- Phoenix - Open-source AI observability with OpenTelemetry tracing and LLM evaluation (380 lines + 2 refs)
🔬 Emerging Techniques (6 skills)
- MoE Training - Mixture of Experts training with DeepSpeed, Mixtral 8x7B, 5× cost reduction (515 lines + 3 refs)
- Model Merging - Combine models with TIES, DARE, SLERP using mergekit (528 lines + 3 refs)
- Long Context - Extend context windows with RoPE, YaRN, ALiBi, 32k-128k tokens (624 lines + 3 refs)
- Speculative Decoding - 1.5-3.6× faster inference with Medusa, Lookahead (379 lines)
- Knowledge Distillation - Compress models 70B→7B with MiniLLM, temperature scaling (424 lines)
- Model Pruning - 50% sparsity with Wanda, SparseGPT, <1% accuracy loss (417 lines)
📝 ML Paper Writing (2 skills)
- ML Paper Writing - Write publication-ready papers for NeurIPS, ICML, ICLR, ACL, AAAI, COLM with LaTeX templates, citation verification, and writing best practices (532 lines + 5 refs)
- Academic Plotting - Generate publication-quality figures for ML papers: architecture diagrams via Gemini AI and data-driven charts via matplotlib/seaborn with venue-specific styling (479 lines + 3 refs)
💡 Ideation (2 skills)
- Research Brainstorming - Structured ideation frameworks for discovering high-impact research directions with 10 complementary lenses (384 lines)
- Creative Thinking - Cognitive science frameworks (bisociation, structure-mapping, constraint manipulation) for genuinely novel research ideas (366 lines)
🧬 Agent-Native Research Artifact (3 skills)
- ARA Compiler - Compiles any research input (PDF papers, repos, experiment logs, raw notes) into a complete Agent-Native Research Artifact with claims, exploration graph, evidence, and code stubs (245 lines + 3 refs)
- ARA Research Manager - Post-task research recorder that runs at session end to extract decisions, experiments, dead ends, and pivots from conversation history into the
ara/directory with user-vs-AI provenance tags (324 lines + 3 refs) - ARA Rigor Reviewer - ARA Seal Level 2 semantic epistemic review scoring six dimensions of research rigor (evidence relevance, falsifiability, scope, coherence, exploration integrity, methodology) with severity-ranked findings (322 lines + 1 ref)
Demos
All 98 skills in this repo are automatically synced to Orchestra Research, where you can add them to your projects with one click and use them with AI research agents.
See skills in action → demos/
We maintain a curated collection of demo repositories showing how to use skills for real AI research tasks:
| Demo | Skills Used | What It Does |
|---|---|---|
| Norm Heterogeneity → LoRA Brittleness | Autoresearch, ML Paper Writing, Ideation | Agent autonomously discovered norm heterogeneity predicts fine-tuning difficulty (r=-0.99), pivoting from a null result on ETF overlaps |
| RL Algorithm Brain Scan | Autoresearch, GRPO, TRL, SAELens, TransformerLens, ML Paper Writing | Agent found DPO is a rank-1 perturbation (95.6% recovery from one SVD direction) while online RL is distributed and structure-preserving |
| NeMo Eval: GPQA Benchmark | NeMo Evaluator | Compare Llama 8B/70B/405B on graduate-level science questions |
| LoRA Without Regret Reproduction | GRPO, TRL | Reproduce SFT + GRPO RL experiments via prompting |
| Layer-Wise Quantization Experiment | llama.cpp, GGUF | Investigate optimal layer precision allocation—early layers at Q8 achieve 1.9× compression with 1.3% perplexity loss |
| Cross-Lingual Alignment Analysis | FAISS | Quantify how well multilingual embeddings align semantic concepts across 8 languages using FAISS similarity search |
| Scientific Plotting Demo | Academic Plotting | Generate publication-quality figures for the Andes QoE-aware LLM serving paper — Gemini AI architecture diagrams + matplotlib data charts (CDF, multi-panel grids, bar charts) |
Featured Demos: Two papers produced entirely by AI agents using the autoresearch skill. The Norm Heterogeneity paper demonstrates autonomous research pivoting — the agent refuted its own hypothesis and discovered a stronger finding. The RL Brain Scan paper demonstrates multi-skill orchestration — the agent trained RL models, analyzed internals with interpretability tools, and synthesized the insight that "DPO is rank-1 alignment." Both papers written end-to-end by the agent.
Skill Structure
Each skill follows a battle-tested format for maximum usefulness:
skill-name/
├── SKILL.md                    # Quick reference (50-150 lines)
│   ├── Metadata (name, description, version)
│   ├── When to use this skill
│   ├── Quick patterns & examples
│   └── Links to references
│
├── references/                 # Deep documentation (300KB+)
│   ├── README.md              # From GitHub/official docs
│   ├── api.md                 # API reference
│   ├── tutorials.md           # Step-by-step guides
│   ├── issues.md              # Real GitHub issues & solutions
│   ├── releases.md            # Version history & breaking changes
│   └── file_structure.md      # Codebase navigation
│
├── scripts/                    # Helper scripts (optional)
└── assets/                     # Templates & examples (optional)
Quality Standards
- 300KB+ documentation from official sources
- Real GitHub issues & solutions (when available)
- Code examples with language detection
- Version history & breaking changes
- Links to official docs
Roadmap
The library spans 98 comprehensive skills across the full AI research lifecycle. See our detailed roadmap for the complete development plan.
View Detailed Statistics
| Metric | Current | Target |
|---|---|---|
| Skills | 87 (high-quality, standardized YAML) | 80 ✅ |
| Avg Lines/Skill | 420 lines (focused + progressive disclosure) | 200-600 lines |
| Documentation | ~130,000 lines total (SKILL.md + references) | 100,000+ lines |
| Gold Standard Skills | 65 with comprehensive references | 50+ |
| Contributors | 1 | 100+ |
| Coverage | Architecture, Tokenization, Fine-Tuning, Mechanistic Interpretability, Data Processing, Post-Training, Safety, Distributed, Optimization, Evaluation, Infrastructure, Inference, Agents, RAG, Multimodal, Prompt Engineering, MLOps, Observability, ML Paper Writing, Ideation, Autoresearch | Full Lifecycle ✅ |
Recent Progress: npm package @orchestra-research/ai-research-skills for one-command installation across all coding agents
Philosophy: Quality > Quantity. Following Anthropic official best practices - each skill provides 200-500 lines of focused, actionable guidance with progressive disclosure.
Repository Structure
claude-ai-research-skills/
├── README.md                    ← You are here
├── CONTRIBUTING.md              ← Contribution guide
├── demos/                       ← Curated demo gallery (links to demo repos)
├── docs/
├── 0-autoresearch-skill/        (1 skill ✓ - Autonomous research orchestration)
├── 01-model-architecture/       (5 skills ✓ - LitGPT, Mamba, RWKV, NanoGPT, TorchTitan)
├── 02-tokenization/             (2 skills ✓ - HuggingFace Tokenizers, SentencePiece)
├── 03-fine-tuning/              (4 skills ✓ - Axolotl, LLaMA-Factory, Unsloth, PEFT)
├── 04-mechanistic-interpretability/ (4 skills ✓ - TransformerLens, SAELens, pyvene, nnsight)
├── 05-data-processing/          (2 skills ✓ - Ray Data, NeMo Curator)
├── 06-post-training/            (8 skills ✓ - TRL, GRPO, OpenRLHF, SimPO, verl, slime, miles, torchforge)
├── 07-safety-alignment/         (4 skills ✓ - Constitutional AI, LlamaGuard, NeMo Guardrails, Prompt Guard)
├── 08-distributed-training/     (6 skills ✓ - Megatron-Core, DeepSpeed, FSDP, Accelerate, Lightning, Ray Train)
├── 09-infrastructure/           (3 skills ✓ - Modal, SkyPilot, Lambda Labs)
├── 10-optimization/             (6 skills ✓ - Flash Attention, bitsandbytes, GPTQ, AWQ, HQQ, GGUF)
├── 11-evaluation/               (3 skills ✓ - lm-evaluation-harness, BigCode, NeMo Evaluator)
├── 12-inference-serving/        (4 skills ✓ - vLLM, TensorRT-LLM, llama.cpp, SGLang)
├── 13-mlops/                    (3 skills ✓ - Weights & Biases, MLflow, TensorBoard)
├── 14-agents/                   (4 skills ✓ - LangChain, LlamaIndex, CrewAI, AutoGPT)
├── 15-rag/                      (5 skills ✓ - Chroma, FAISS, Sentence Transformers, Pinecone, Qdrant)
├── 16-prompt-engineering/       (4 skills ✓ - DSPy, Instructor, Guidance, Outlines)
├── 17-observability/            (2 skills ✓ - LangSmith, Phoenix)
├── 18-multimodal/               (7 skills ✓ - CLIP, Whisper, LLaVA, Stable Diffusion, SAM, BLIP-2, AudioCraft)
├── 19-emerging-techniques/      (6 skills ✓ - MoE, Model Merging, Long Context, Speculative Decoding, Distillation, Pruning)
├── 20-ml-paper-writing/         (2 skills ✓ - ML Paper Writing with LaTeX templates, Academic Plotting)
├── 21-research-ideation/           (2 skills ✓ - Research Brainstorming, Creative Thinking)
├── 22-agent-native-research-artifact/ (3 skills ✓ - ARA Compiler, Research Manager, Rigor Reviewer)
└── packages/ai-research-skills/ (npm package for one-command installation)
Use Cases
For Researchers
"I need to fine-tune Llama 3 with custom data" → 03-fine-tuning/axolotl/ - YAML configs, 100+ model support
For ML Engineers
"How do I optimize inference latency?" → 12-inference-serving/vllm/ - PagedAttention, batching
For Students
"I want to learn how transformers work" → 01-model-architecture/litgpt/ - Clean implementations
For Teams
"We need to scale training to 100 GPUs" → 08-distributed-training/deepspeed/ - ZeRO stages, 3D parallelism
License
MIT License - See LICENSE for details.
Note: Individual skills may reference libraries with different licenses. Please check each project's license before use.
Citation
If you use AI Research Skills in your work or find it helpful for a publication, we'd appreciate a citation:
BibTeX
@software{ai_research_skills,
  title     = {AI Research Skills Library},
  author    = {{Orchestra Research}},
  year      = {2025},
  url       = {https://github.com/orchestra-research/AI-research-SKILLs},
  note      = {Open-source skills library enabling AI agents to autonomously conduct AI research}
}
APA
Orchestra Research. (2025). AI Research Skills Library [Computer software]. https://github.com/orchestra-research/AI-research-SKILLs
Chicago
Orchestra Research. "AI Research Skills Library." GitHub, 2025. https://github.com/orchestra-research/AI-research-SKILLs.
IEEE
Orchestra Research, "AI Research Skills Library," 2025. [Online]. Available: https://github.com/orchestra-research/AI-research-SKILLs
Tip: You can also click "Cite this repository" in the GitHub sidebar for auto-formatted citations.
Acknowledgments
Built with:
- Claude Code - AI pair programming
- Skill Seeker - Automated doc scraping
- Open Source AI Community - For amazing tools and docs
Special thanks to:
- EleutherAI, HuggingFace, NVIDIA, Lightning AI, Meta AI, Anthropic
- All researchers who maintain excellent documentation
Contributors
Thanks to all the people who have contributed to the AI Research Skills Library:
We welcome contributions from the AI research community! See CONTRIBUTING.md for detailed guidelines on:
- Adding new skills
- Improving existing skills
- Quality standards and best practices
- Submission process
Recent Updates
June 2026 - v1.7.1 🧹 Inventory Consistency, Drift Guard & Security Hardening
- 📊 Repo-wide inventory reconciled to 98 skills / 23 categories — corrected stale counts that had drifted apart across files: CLAUDE.md (said 90), CONTRIBUTING.md (said 86/22), the README sync line (said 87), WELCOME.md and the npm package README (said 86/22). Also fixed wrong per-category listings (TorchTitan, SwanLab, A-Evolve, ML Training Recipes, Cosmos Policy/OpenPI/OpenVLA-OFT, the paper-writing skills)
- 🛡️ New CI drift guard —
scripts/check-inventory.sh+check-inventory.ymlfail CI whenever the documented skill/category counts diverge from the actualSKILL.mdcount on disk, so the inventory can't silently drift again - 📦 Marketplace sync hardening —
sync-skills.ymlnow prunes build artifacts (node_modules/__pycache__/*.pyc/.ipynb_checkpoints) before zipping and fails loudly above 190 files instead of hitting the marketplace's 200-file rejection - 🔒 Security — pinned CLI dependencies (
chalk/inquirer/ora) to exact, patched versions with a regenerated lockfile (inquirer@9.3.8clears thetmppath-traversal advisory;npm auditnow reports 0 vulnerabilities) - 🧹 Full open PR/issue triage pass against scope + contribution standards
April 2026 - v1.6.0 🧬 Agent-Native Research Artifact (ARA) — 23rd Category, 98 Skills
- 🧬 NEW CATEGORY:
22-agent-native-research-artifact/(the 23rd category) — three skills that turn research outputs into a falsifiable, agent-traversable artifact:- 🛠️ ARA Compiler — compiles any input (PDF papers, GitHub repos, experiment logs, raw notes) into a structured ARA with cognitive layer (claims, concepts, heuristics), physical layer (configs, code stubs), exploration graph (research DAG), and grounded evidence
- 📋 ARA Research Manager — post-task epilogue that scans conversation history at session end and writes decisions, experiments, dead ends, claims, heuristics, and pivots into the
ara/directory withuser/ai-suggested/ai-executed/user-revisedprovenance tags - 🔍 ARA Rigor Reviewer — Seal Level 2 semantic epistemic review scoring six dimensions of research rigor (evidence relevance, falsifiability, scope calibration, argument coherence, exploration integrity, methodological rigor) and emitting a severity-ranked report with a Strong Accept-to-Reject recommendation
- 🔗 Sourced from the Agent-Native-Research-Artifact-Init reference repo, restructured to AI-research-SKILLs standards (kebab-case names, third-person descriptions, Title-Case tags, one-level-deep references)
- 🧩 Plugin entry
agent-native-research-artifactadded to.claude-plugin/marketplace.json; CLI category registered as22-agent-native-research-artifactwith three individual skill entries in the npm installer - 🔄 Auto-syncs to Orchestra marketplace via
sync-skills.ymlon push; npm package republished as@orchestra-research/ai-research-skills@1.6.0viapublish-npm.ymlon version bump - 📊 98 total skills across 23 categories — full lifecycle from idea → paper → falsifiable, auditable artifact
March 2026 - v1.4.0 🔬 Autoresearch & 86 Skills — Full Research Lifecycle
- 🔬 NEW SKILL: Autoresearch — autonomous research orchestration using a two-loop architecture (inner optimization loop + outer synthesis loop)
- 🧠 Manages the full research lifecycle: literature survey → ideation → experiments → synthesis → paper writing
- 🔄 Routes to all 86 domain skills automatically — agents don't need to know which skill to use
- ⏰ Mandatory
/loop(Claude Code) and cron job (OpenClaw) for continuous autonomous operation - 📊 Generates research presentations (HTML/PDF) with optimization trajectory plots for human review
- 📝 Findings.md as persistent project memory across sessions with "Lessons and Constraints" tracking
- 🗂️ Structured workspace: research-state.yaml, findings.md, research-log.md, literature/, experiments/, src/, data/, to_human/
- 📄 Two demo papers produced by autoresearch: Norm Heterogeneity → LoRA Brittleness and RL Algorithm Brain Scan
- 🚀 WELCOME.md for cold-start agent bootstrap — one URL to go from zero to autonomous research
- 📦 npm v1.4.x with Windows symlink fallback, all 22 categories installable
- 🤖 Supported agents: Claude Code, Hermes Agent, OpenCode, OpenClaw, Qoder, Cursor, Codex, Gemini CLI, Qwen Code
- 📊 87 total skills across 22 categories — complete research lifecycle coverage
February 2026 - v0.15.0 🛡️ Prompt Guard & 83 Skills
- 🛡️ NEW SKILL: Prompt Guard - Meta's 86M prompt injection & jailbreak detector
- ⚡ 99%+ TPR, <1% FPR, <2ms GPU latency, multilingual (8 languages)
- 🔒 3 workflows: user input filtering, third-party data filtering, batch RAG processing
- 📊 83 total skills across 20 categories
January 2026 - v0.14.0 📦 npm Package & 82 Skills
- 📦 NEW:
npx @orchestra-research/ai-research-skills- One-command installation for all coding agents - 🤖 Supported agents: Claude Code, OpenCode, Cursor, Codex, Gemini CLI, Qwen Code
- ✨ Interactive installer with category/individual skill selection
- 🔄 Update installed skills, selective uninstall
- 📊 82 total skills (5 new post-training skills: verl, slime, miles, torchforge + TorchTitan)
- 🏗️ Megatron-Core moved to Distributed Training category
January 2026 - v0.13.0 📝 ML Paper Writing & Demos Gallery
- 📝 NEW CATEGORY: ML Paper Writing (20th category, 77th skill)
- 🎯 Write publication-ready papers for NeurIPS, ICML, ICLR, ACL, AAAI, COLM
- 📚 Writing philosophy from top researchers (Neel Nanda, Farquhar, Gopen & Swan, Lipton, Perez)
- 🔬 Citation verification workflow - never hallucinate references
- 📄 LaTeX templates for 6 major conferences
- 🎪 NEW: Curated demos gallery (
demos/) showcasing skills in action - 🔗 Demo repos: NeMo Evaluator benchmark, LoRA Without Regret reproduction
- 📖 936-line comprehensive SKILL.md with 4 workflows
January 2026 - v0.12.0 📊 NeMo Evaluator SDK
- 📊 NEW SKILL: NeMo Evaluator SDK for enterprise LLM benchmarking
- 🔧 NVIDIA's evaluation platform with 100+ benchmarks from 18+ harnesses (MMLU, HumanEval, GSM8K, safety, VLM)
- ⚡ Multi-backend execution: local Docker, Slurm HPC, Lepton cloud
- 📦 Container-first architecture for reproducible evaluation
- 📝 454 lines SKILL.md + 4 comprehensive reference files (~48KB documentation)
December 2025 - v0.11.0 🔬 Mechanistic Interpretability
- 🔬 NEW CATEGORY: Mechanistic Interpretability (4 skills)
- 🔍 TransformerLens skill: Neel Nanda's library for mech interp with HookPoints, activation caching, circuit analysis
- 🧠 SAELens skill: Sparse Autoencoder training and analysis for feature discovery, monosemanticity research
- ⚡ pyvene skill: Stanford's causal intervention library with declarative configs, DAS, activation patching
- 🌐 nnsight skill: Remote interpretability via NDIF, run experiments on 70B+ models without local GPUs
- 📝 ~6,500 new lines of documentation across 16 files
- 76 total skills (filling the missing 04 category slot)
November 25, 2025 - v0.10.0 🎉 70 Skills Complete!
- 🎉 ROADMAP COMPLETE: Reached 70-skill milestone!
- 🚀 Added 4 skills: Lambda Labs, Segment Anything (SAM), BLIP-2, AudioCraft
- ☁️ Lambda Labs skill: Reserved/on-demand GPU cloud with H100/A100, persistent filesystems, 1-Click Clusters
- 🖼️ SAM skill: Meta's Segment Anything for zero-shot image segmentation with points/boxes/masks
- 👁️ BLIP-2 skill: Vision-language pretraining with Q-Former, image captioning, VQA
- 🎵 AudioCraft skill: Meta's MusicGen/AudioGen for text-to-music and text-to-sound generation
- 📝 ~10,000 new lines of documentation across 12 files
- 70 total skills (100% roadmap complete!)
November 25, 2025 - v0.9.0
- 🚀 Added 2 infrastructure skills: Modal, SkyPilot
- ☁️ Modal skill: Serverless GPU cloud with Python-native API, T4-H200 on-demand, auto-scaling
- 🌐 SkyPilot skill: Multi-cloud orchestration across 20+ providers with spot recovery
- ✨ New Infrastructure category (2 skills - serverless GPU and multi-cloud orchestration)
- 📝 ~2,500 new lines of documentation across 6 files
- 66 total skills (94% towards 70-skill target)
November 25, 2025 - v0.8.0
- 🚀 Added 5 high-priority skills: HQQ, GGUF, Phoenix, AutoGPT, Stable Diffusion
- ⚡ HQQ skill: Half-Quadratic Quantization without calibration data, multi-backend support
- 📦 GGUF skill: llama.cpp quantization format, K-quant methods, CPU/Metal inference
- 👁️ Phoenix skill: Open-source AI observability with OpenTelemetry tracing and LLM evaluation
- 🤖 AutoGPT skill: Autonomous AI agent platform with visual workflow builder
- 🎨 Stable Diffusion skill: Text-to-image generation via Diffusers, SDXL, ControlNet, LoRA
- 📝 ~9,000 new lines of documentation across 15 files
- 64 total skills (91% towards 70-skill target)
November 25, 2025 - v0.7.0
- 🚀 Added 5 high-priority skills: PEFT, CrewAI, Qdrant, AWQ, LangSmith
- ✨ New Observability category with LangSmith for LLM tracing and evaluation
- 🎯 PEFT skill: Parameter-efficient fine-tuning with LoRA, QLoRA, DoRA, 25+ methods
- 🤖 CrewAI skill: Multi-agent orchestration with role-based collaboration
- 🔍 Qdrant skill: High-performance Rust vector search with hybrid filtering
- ⚡ AWQ skill: Activation-aware 4-bit quantization with minimal accuracy loss
- 📝 ~8,000 new lines of documentation across 15 files
- 59 total skills (84% towards 70-skill target)
November 15, 2025 - v0.6.0
- 📊 Added 3 comprehensive MLOps skills: Weights & Biases, MLflow, TensorBoard
- ✨ New MLOps category (3 skills - experiment tracking, model registry, visualization)
- 📝 ~10,000 new lines of documentation across 13 files
- 🔧 Comprehensive coverage: experiment tracking, hyperparameter sweeps, model registry, profiling, embeddings visualization
- 54 total skills (77% towards 70-skill target)
November 12, 2025 - v0.5.0
- 🎯 Added 4 comprehensive prompt engineering skills: DSPy, Instructor, Guidance, Outlines
- ✨ New Prompt Engineering category (4 skills - DSPy, Instructor, Guidance, Outlines)
- 📝 ~10,000 new lines of documentation across 16 files
- 🔧 Comprehensive coverage: declarative programming, structured outputs, constrained generation, FSM-based generation
- 47 total skills (67% towards 70-skill target)
November 9, 2025 - v0.4.0
- 🤖 Added 11 comprehensive skills: LangChain, LlamaIndex, Chroma, FAISS, Sentence Transformers, Pinecone, CLIP, Whisper, LLaVA
- ✨ New Agents category (2 skills - LangChain, LlamaIndex)
- 🔍 New RAG category (4 skills - Chroma, FAISS, Sentence Transformers, Pinecone)
- 🎨 New Multimodal category (3 skills - CLIP, Whisper, LLaVA)
- 📝 ~15,000 new lines of documentation
- 43 total skills (61% towards 70-skill target)
November 8, 2025 - v0.3.0
- 🚀 Added 8 comprehensive skills: TensorRT-LLM, llama.cpp, SGLang, GPTQ, HuggingFace Tokenizers, SentencePiece, Ray Data, NeMo Curator
- ⚡ Completed Inference & Serving category (4/4 skills)
- 🔤 New Tokenization category (2 skills)
- 📊 New Data Processing category (2 skills)
- 📝 9,617 new lines of documentation across 30 files
- 32 total skills (45% towards 70-skill target)
November 6, 2025 - v0.2.0
- Added 10 skills from GitHub (Megatron-Core, Lightning, Ray Train, etc.)
- Improved skill structure with comprehensive references
- Created strategic roadmap to 70 skills
- Added contribution guidelines
November 3, 2025 - v0.1.0
- 🎉 Initial release with 5 fine-tuning skills
Community
Join our community to stay updated, ask questions, and connect with other AI researchers:
- SkillEvolve Meta-Skill - Connect your agent to the collective intelligence of the community. Captures techniques discovered during sessions and shares them back as curated skills.
- Slack Community - Chat with the team and other users
- Twitter/X - Follow for updates and announcements
- LinkedIn - Connect professionally
Star History
Questions
What is Orchestra-Research/AI-Research-SKILLs?
Comprehensive open-source library of AI research and engineering skills for any AI model. Package the skills and your claude code/codex/gemini agent will be an AI research agent with full horsepower…
How do I install AI-Research-SKILLs?
Run "npx skills add Orchestra-Research/AI-Research-SKILLs" and choose the skills you want. Many packs also document their own install path (for example a Claude Code plugin marketplace) in the README below.
How many skills are in AI-Research-SKILLs?
98 SKILL.md skills. Alyn lists 40 of them with their own pages.