
@ai-evals-course
ai-evals-course
- Skills
- 9
- GitHub stars
- 1.7k
- Installs
- 9.7k
Top skills by ai-evals-course
 ai-evals-course
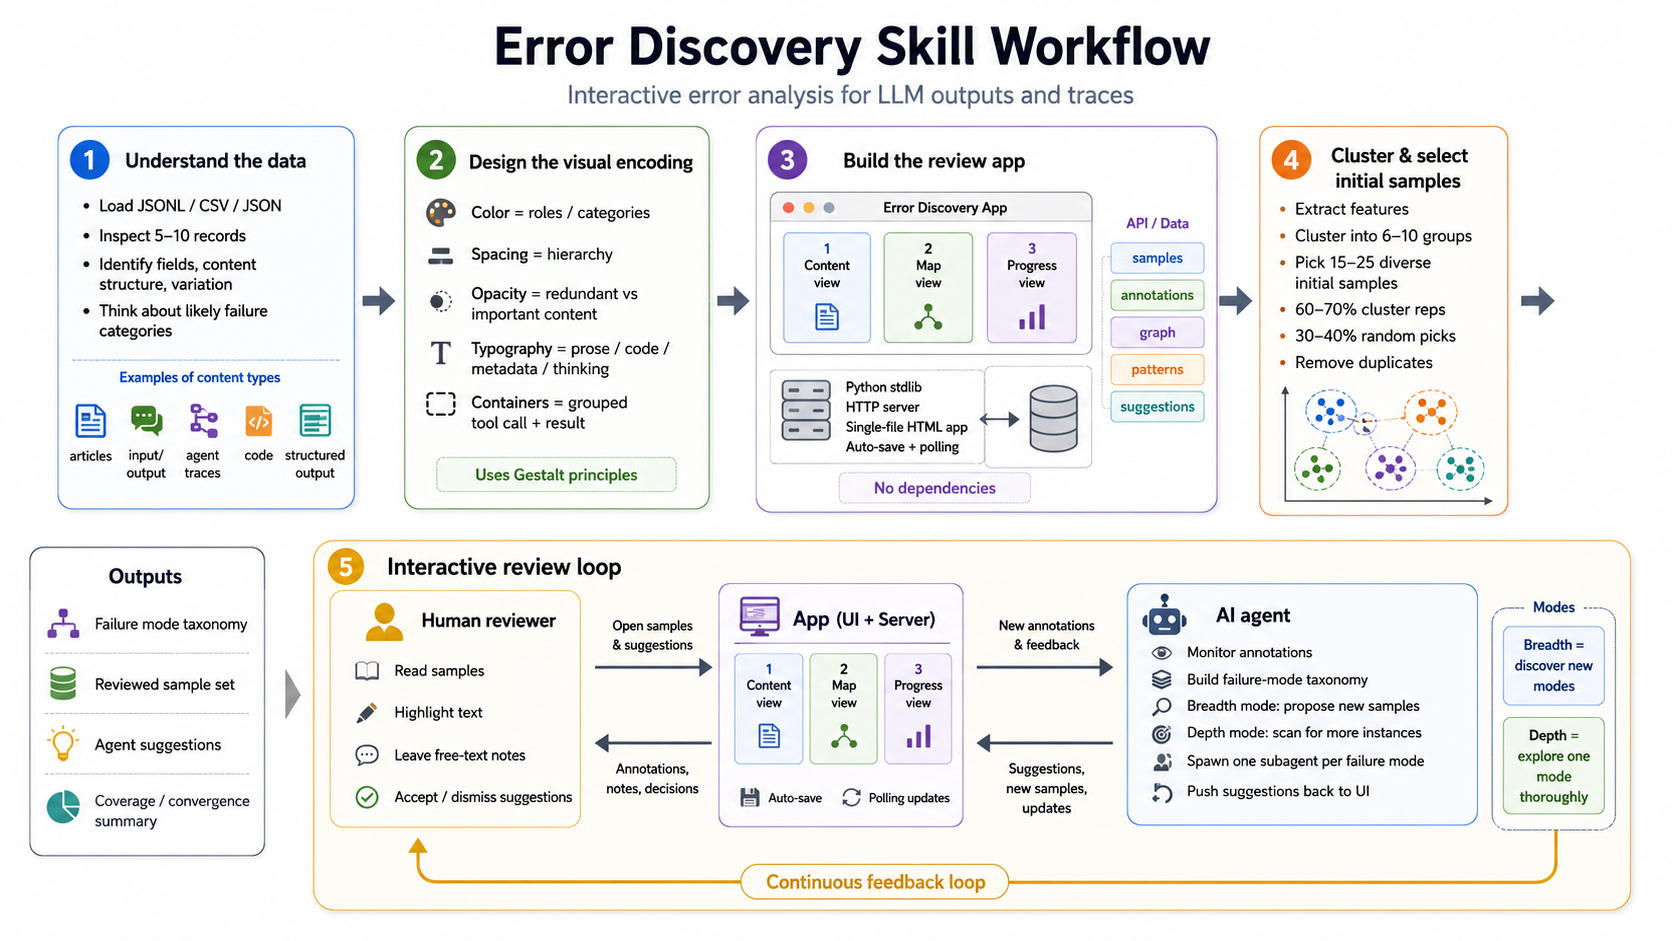
error-discovery
Run error analysis on a dataset. Build a review UI, select diverse samples, monitor annotations, and organize failure modes.
ai-evals-courseeval-audit
Audit an LLM eval pipeline and surface problems: missing error analysis, unvalidated judges, vanity metrics, etc. Use when inheriting an eval system, when unsure whether evals are…
ai-evals-courseevaluate-rag
Guides evaluation of RAG pipeline retrieval and generation quality. Use when evaluating a retrieval-augmented generation system, measuring retrieval quality, assessing generation…
ai-evals-coursevalidate-evaluator
Calibrate an LLM judge against human labels using data splits, TPR/TNR, and bias correction. Use after writing a judge prompt (write-judge-prompt) when you need to verify alignment before…
ai-evals-coursewrite-judge-prompt
Design LLM-as-Judge evaluators for subjective criteria that code-based checks cannot handle. Use when a failure mode requires interpretation (tone, faithfulness, relevance, completeness)…
ai-evals-coursebuild-review-interface
Build a custom browser-based annotation interface tailored to your data for reviewing LLM traces and collecting structured feedback. Use when you need to build an annotation tool, review…
ai-evals-coursegenerate-synthetic-data
Create diverse synthetic test inputs for LLM pipeline evaluation using dimension-based tuple generation. Use when bootstrapping an eval dataset, when real user data is sparse, or when…
ai-evals-courseevals-start
Entry point for evals. Use when the user asks for help with evals, does not know where to begin, or asks for something no other skill in this plugin matches. Do NOT use when a more specific…
ai-evals-coursewrite-code-eval
Write code evaluators for known failure modes with objective rules. Use when code can check the rule from a trace, with or without a reference answer. Use `write-judge-prompt` when the rule…